Talk to sales.
A drawing on pale paper of one upright phone, outlined in grey, whose otherwise empty screen holds a single glowing mint dot near the centre.
Five white cards sit around the paper, each carrying one ink icon for a database, a refresh arrow, a circled mark, a bar chart and a person, and the mint dot glows against the top edge of the bar chart card.
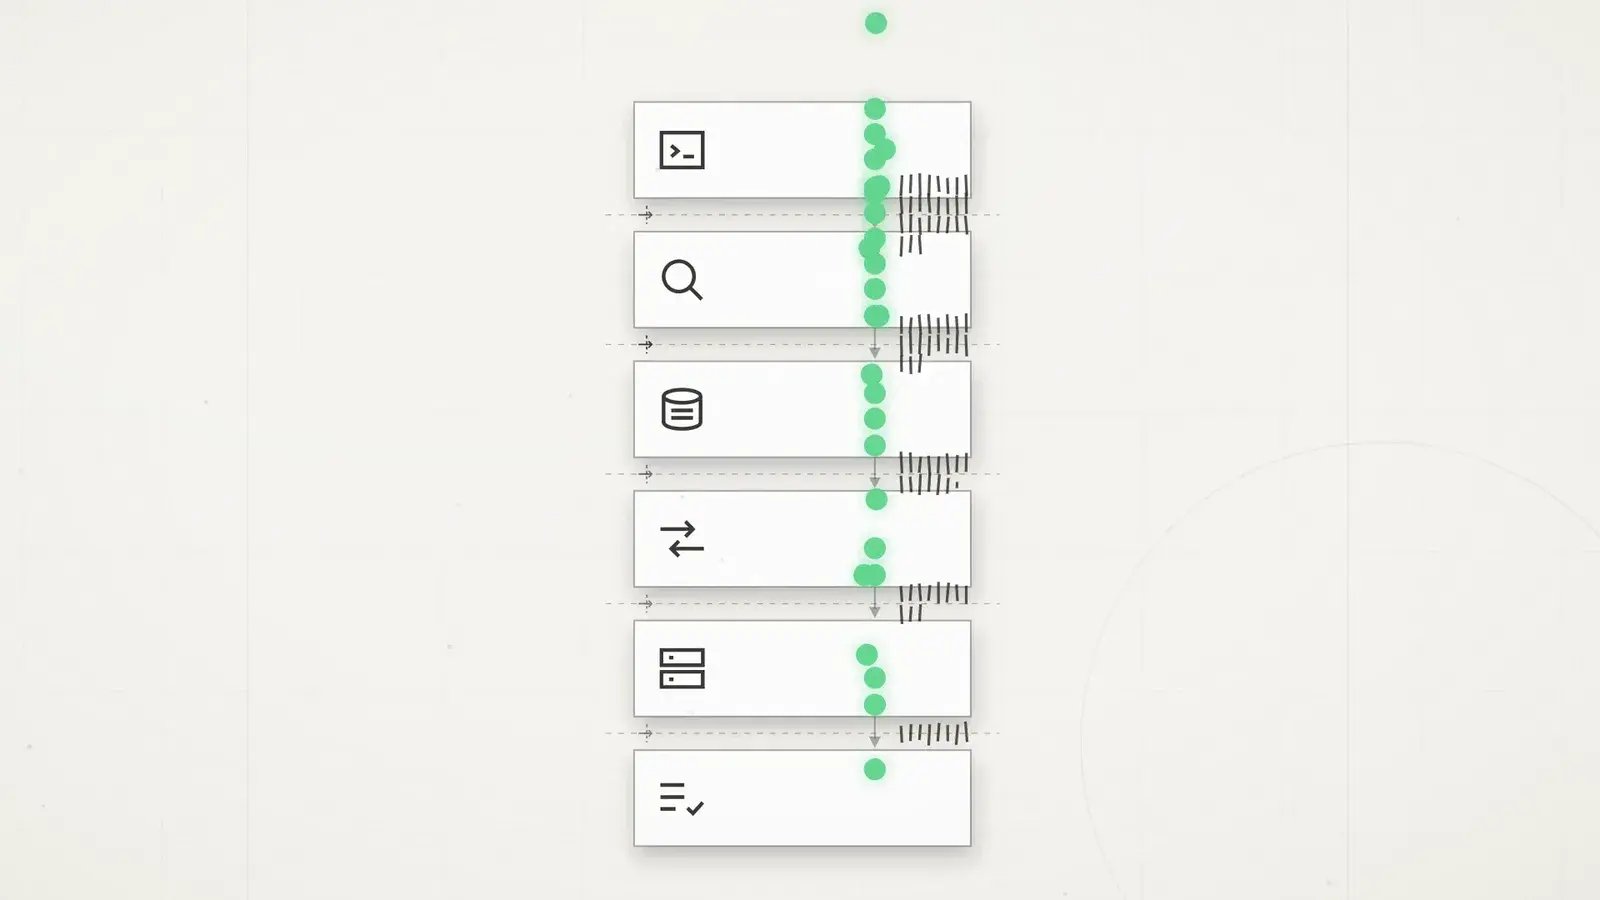
Six white boxes are stacked in one column, each with an ink icon for a prompt, a magnifier, a database, an exchange, a server and a checked list, with five dashed boundary lines crossing between them, a cluster of ink tick marks beside every boundary, and mint dots packed nose to tail down the whole column.
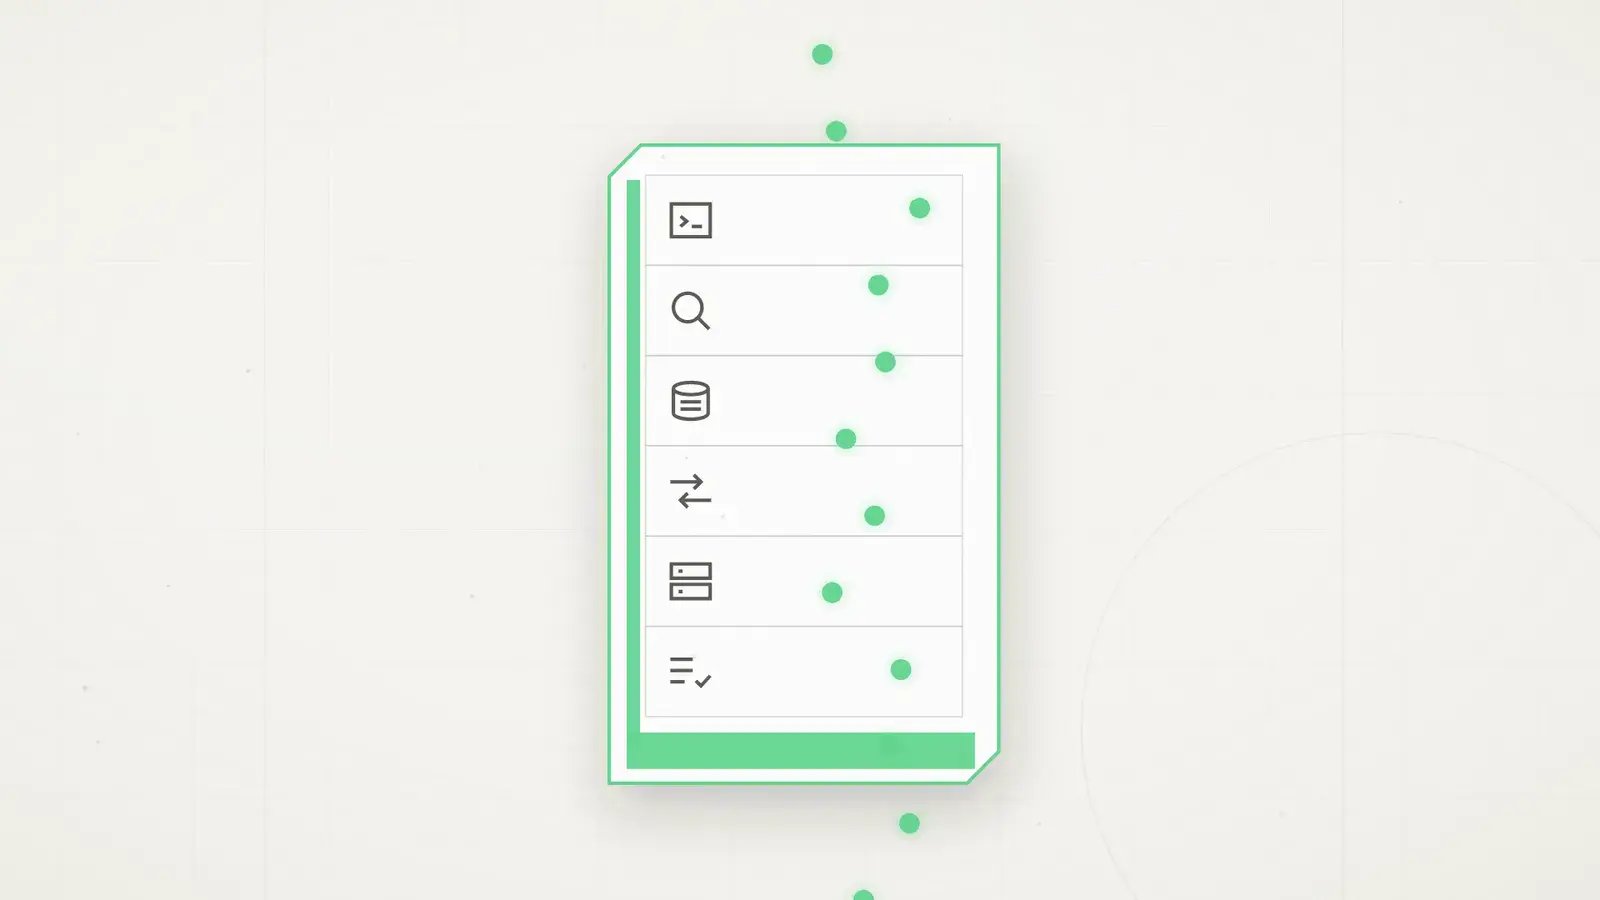
The six boxes have folded into one tall card edged in mint, its six icons now rows divided by hairlines, and the mint dots wind down through it with no boundary left to cross.
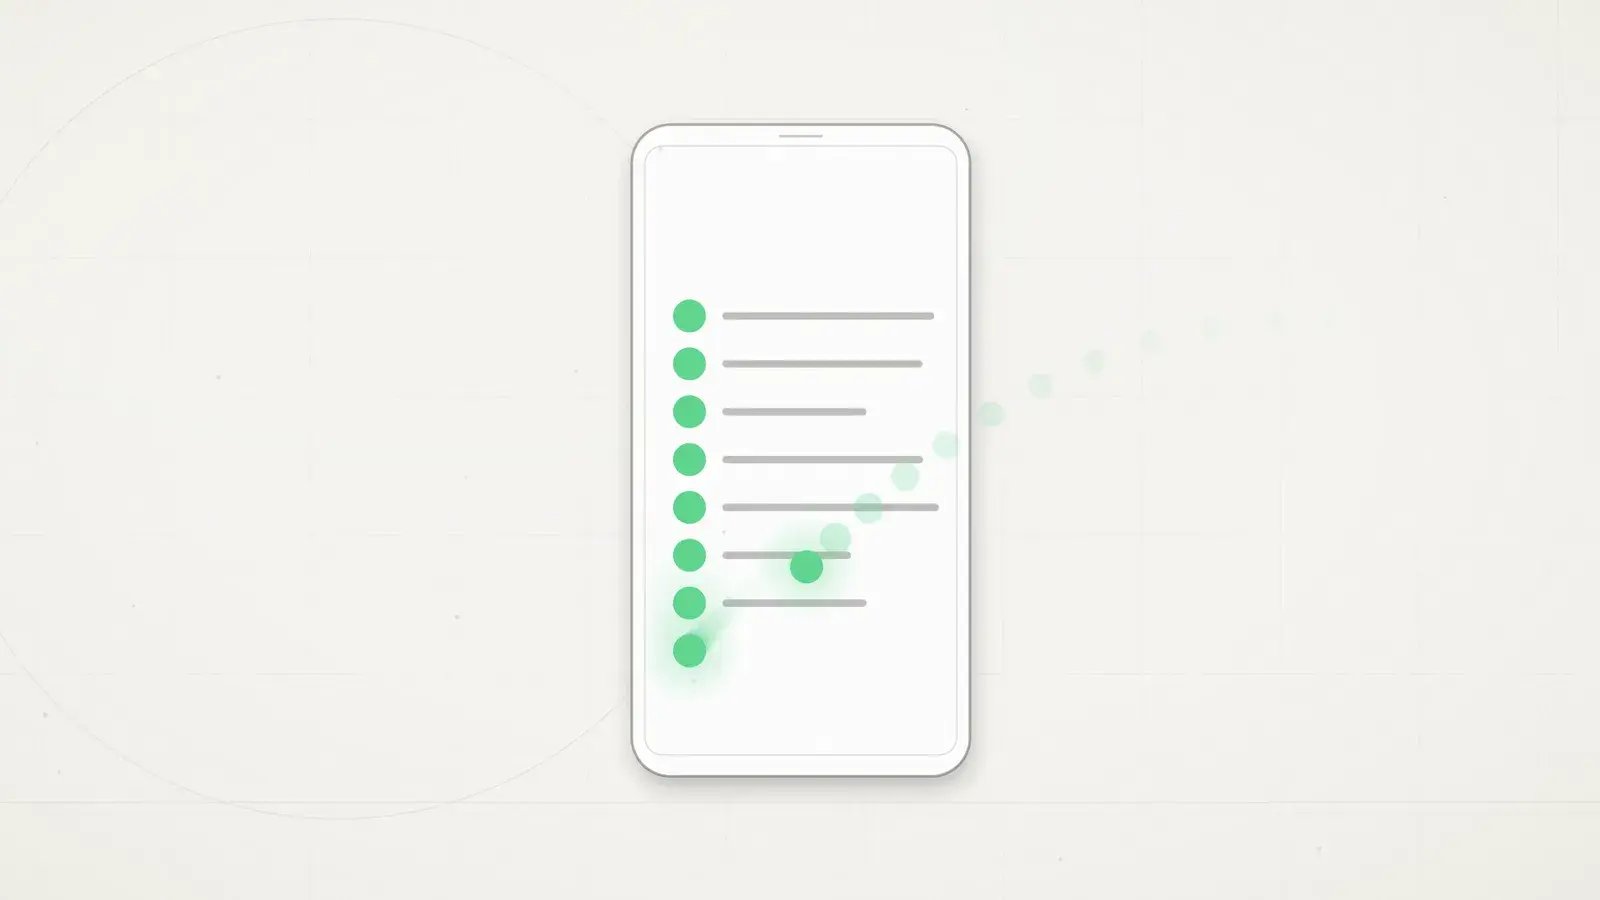
The phone returns with eight mint dots stacked down the left of its screen, seven of them already beside a short grey bar of an answer, and a trail of fainter dots curving in from the right to join them.

Travel


Building Intelligent Travel Experiences

Why AI Search Is Transforming Travel Discovery

Introduction489 wordsRead the section

Retrieval Engineering

Prompt engineering influences how a model reasons. Retrieval engineering determines what it has to reason about.

Retrieval Engineering257 wordsRead the section

The Limits of Fragmented Architectures

The problem is no longer vector search. It's fragmented AI architectures.

The Limits of Fragmented Architectures359 wordsRead the section

The AI Search Platform

Every successful AI Search Platform solves the same four engineering problems.

The AI Search Platform860 wordsRead the section

Ready to Build Intelligent Travel Applications?

Whether you're modernizing travel search, adding AI-powered recommendations, or planning for AI agents, we'd be happy to discuss your architecture, answer technical questions, and explore how Vespa can help you build the next generation of intelligent travel applications.

Talk to sales. Retrieval Engineering in Practice453 wordsRead the section

The full document

One request


Introduction

About this eBook

Who should read this ebook?

This eBook is written for organizations delivering intelligent travel discovery and booking experiences, including:

  • Airlines & Airline Retailing
  • Hotels & Hospitality
  • Loyalty & Rewards Platforms
  • Online Travel Agencies (OTAs)
  • Travel Marketplaces
  • Travel Technology Providers

Although these organizations serve different markets, they share many of the same AI search, ranking, personalization, and retrieval engineering challenges—and many of the same architectural solutions.

Every travel application is becoming an AI application.

Travelers increasingly expect AI to understand intent, compare alternatives, build itineraries, and answer complex travel questions. As travel discovery evolves from search to intelligent planning, Retrieval Engineering is becoming the discipline that enables AI search, recommendations, personalization, and AI agents to work together at scale. Delivering these experiences requires more than adding a large language model. AI applications must retrieve, rank, and continuously update information across travel inventory, traveler preferences, pricing, loyalty programs, reviews, and operational data with predictable latency and complete trust in the results. This is where AI Search Platforms emerge. Rather than stitching together vector databases, search engines, rerankers, and inference services, they unify the entire retrieval workflow within a single architecture, reducing complexity while improving relevance, scalability, and infrastructure efficiency. This eBook explores how travel organizations are building the next generation of intelligent travel applications. It introduces the principles of Retrieval Engineering, explains why unified AI Search Platforms are replacing fragmented AI architectures, and shows how organizations are preparing for AI search, conversational experiences, and AI agents.

Introduction

AI is Changing Travel Discovery

Travel companies are entering a new phase of AI adoption. Customers no longer expect travel applications to simply return lists of flights, hotels, or destinations. They increasingly expect intelligent applications that understand intent, answer questions, recommend alternatives, and help them plan and book increasingly complex journeys. This shift is transforming travel discovery. Search, recommendations, personalization, and conversational AI are converging into a single intelligent experience that continuously adapts to traveler preferences, real-time inventory, pricing, loyalty programs, and business priorities.

Why Now?

The emergence of AI agents represents the next major evolution. Rather than simply returning recommendations, intelligent travel applications will investigate alternatives, refine itineraries, compare trade-offs, and adapt plans as new information becomes available. These increasingly sophisticated workflows place far greater demands on the underlying search infrastructure than traditional search applications were ever designed to support. For travel organizations, this creates a significant opportunity. Those that successfully combine AI search, personalization, and trusted travel data will deliver richer traveler experiences, increase engagement and conversion, and differentiate themselves in an increasingly competitive market. As AI becomes the primary interface to travel discovery, the quality of search increasingly determines the quality of the customer experience.

AI Creates New Travel Experiences

Leading travel organizations are adding AI search, recommendations, conversational experiences, and AI agents to customer-facing applications.

The challenge is no longer deciding whether to adopt AI—but building the retrieval architecture required to deliver these experiences efficiently at scale.
Everything it needs


Retrieval Engineering

Retrieval Engineering

Prompt engineering influences how a model reasons. Retrieval engineering determines what it has to reason about.

Search engineering has always balanced competing priorities: relevance, performance, scalability, and cost. AI raises the stakes considerably. Instead of retrieving information for people to evaluate, retrieval systems increasingly assemble the context that large language models and AI agents use to reason, generate, and act. Every retrieval decision becomes part of an automated workflow where quality, latency, and freshness directly influence the outcome.

This shift has given rise to a new engineering discipline: Retrieval Engineering. It is the practice of designing, optimizing, and operating retrieval workflows that balance search quality, latency, freshness, scalability, and infrastructure cost. Rather than focusing on individual technologies such as vector databases, rerankers, or inference services, it treats the retrieval workflow as a single system whose components must work together efficiently.

Retrieval workflows orchestrate multiple retrieval techniques, ranking models, and relevance signals, including:

  • Hybrid retrieval (keyword, semantic, and structured data)
  • Structured filtering and business rules
  • Query rewriting and expansion
  • Personalization
  • Machine-learned ranking
  • Real-time updates
  • Machine learning inference
  • Context assembly for language models and AI agents

Each capability improves retrieval but also adds computational cost and architectural complexity. Retrieval Engineering determines where these techniques add value and how to execute them efficiently at scale. As AI applications evolve from conversational assistants to deep research systems and autonomous agents, a single request may trigger hundreds of retrieval operations, making workflow efficiency essential for accurate, responsive, and cost-effective AI applications.

But what does an effective retrieval workflow look like?

The chain


The Limits of Fragmented Architectures

The Limits of Fragmented Architectures

Vector databases solved an important problem: making semantic retrieval practical at scale. They have become an essential building block for AI applications, allowing systems to retrieve information based on meaning rather than exact keyword matches.

But retrieval is only one stage of a much larger workflow.

As AI applications mature, they quickly outgrow semantic retrieval alone. High-quality AI systems increasingly combine keyword search, structured filtering, business rules, machine-learned ranking, real-time updates, and inference to assemble accurate context before a language model generates a response. The engineering challenge shifts from selecting the right retrieval technology to orchestrating an increasingly sophisticated retrieval workflow.

Many organizations address this by integrating specialized technologies. A vector database provides semantic retrieval. A search engine handles keyword matching. Additional services provide reranking, filtering, personalization, and machine-learning inference. This approach works well initially, but every new component introduces another network hop, another operational dependency, and another source of latency.

The problem is no longer vector search. It's fragmented AI architectures.

As search evolved, engineers naturally adopted best-of-breed architectures, combining specialized technologies to improve retrieval quality. While this delivered increasingly capable applications, it also introduced additional latency, operational complexity, and infrastructure cost. As AI workloads grow, those trade-offs become increasingly difficult to justify.

Vector databases remain an essential part of retrieval, but semantic similarity alone rarely determines the best result. High-quality AI applications combine vector similarity with exact keyword matching, structured filters, business rules, behavioral signals, freshness, authority, and machine-learned ranking to retrieve the most relevant information.

This is particularly important for domain-specific applications, where precise terminology, proprietary vocabularies, and structured business data often carry as much weight as semantic similarity. Retrieval quality depends not only on the embedding model, but on how effectively all of these signals work together.

Many vector databases including AI search architectures built around Lucene-based search engines address individual parts of this workflow extremely well. The engineering challenge is bringing those capabilities together into a retrieval architecture that remains efficient, scalable, and operationally simple as AI applications evolve.

The next evolution isn't another retrieval component. It's a platform that executes the entire retrieval workflow as a single system.

One engine


The AI Search Platform

The AI Search Platform

AI Search Platforms have become the execution layer for search applications—from traditional search and recommendations to answer engines and AI agents. Rather than assembling retrieval workflows from multiple specialized systems, they integrate retrieval, ranking, machine-learning inference, and real-time serving into a single architecture.

This unified approach enables organizations to execute the entire retrieval workflow as one system, reducing operational complexity while improving search quality, scalability, and infrastructure efficiency. As AI applications become more sophisticated, the platform, rather than the individual components, becomes the foundation for delivering fast, accurate, and trustworthy results.

Vespa is an AI Search Platform built for Retrieval Engineering, enabling customer-facing intelligent applications to deliver fast, trustworthy, and scalable AI experiences.

Building the Retrieval Workflow

Retrieval Engineering defines the principles. The AI Search Platform provides the solution.

Retrieval workflows combine keyword search, semantic retrieval, structured filtering, machine-learned ranking, real-time updates, and business logic into a single execution path. The challenge is not implementing any one of these capabilities in isolation—it's executing them together with predictable latency, operational simplicity, and infrastructure efficiency.

Rather than assembling independent services for retrieval, ranking, filtering, and inference, Vespa executes the entire retrieval workflow within a single distributed serving engine. This unified approach reduces unnecessary data movement, simplifies operations, and enables intelligent applications to scale without adding infrastructure.

Every successful AI Search Platform solves the same four engineering problems.

1. Unified Retrieval

Retrieval identifies candidates.

Retrieval is no longer simply about finding semantically similar documents. AI applications depend on retrieving the right amount of relevant context before reasoning begins. Modern retrieval workflows combine dense vector search, keyword search, structured filtering, metadata, and business rules to identify, rank, and assemble that context.

Vector databases solved an important problem by making semantic retrieval practical, but vector similarity alone rarely determines the best result. High-quality retrieval depends on combining multiple retrieval techniques within a single query.

Vespa executes hybrid retrieval natively, combining vectors, text, and structured data in a single distributed query. Because all retrieval methods execute where the data resides, complex hybrid queries avoid unnecessary network hops, maintaining predictable performance while lowering infrastructure costs.

This enables applications to combine semantic understanding with exact terminology, structured metadata, recency, authority, and other domain-specific signals to deliver more accurate retrieval.

Retrieval workflows have evolved beyond single-vector representations. Techniques such as late interaction, multi-vector retrieval, multimodal retrieval, and visual document understanding require richer representations than a single embedding can provide. Vespa's tensor-native architecture was designed for these emerging retrieval techniques, enabling sophisticated retrieval models to execute within the same distributed platform.

2. Intelligent Ranking

Ranking determines which information reaches the user or the language model.

As AI increasingly consumes retrieved information directly, ranking becomes as important as retrieval. Rather than presenting a short list of results for a person to evaluate, AI retrieval must identify and assemble the right amount of relevant context for language models and AI agents. Ranking therefore determines not only which information is retrieved, but which context is ultimately used for reasoning, generation, and decision-making.

Applying sophisticated ranking models to every candidate would quickly become prohibitively expensive. Vespa uses multi-phase ranking to progressively refine candidate sets, applying increasingly sophisticated ranking models, including machine-learning inference, only where they improve the final result.

Because ranking executes locally where the data resides, inference scales naturally with the cluster while minimizing network overhead. The result is higher search quality without sacrificing throughput, latency, or infrastructure efficiency.

3. Continuous Freshness

AI applications are only as trustworthy as the information they retrieve.

Modern AI applications operate in constantly changing environments where documents, customer data, embeddings, user behavior, and machine-learning models evolve continuously. Delayed updates quickly become stale retrieval, leading directly to poorer recommendations, outdated answers, and less reliable AI systems.

Vespa continuously indexes and updates structured data, text, vectors, and machine-learning models while serving live traffic. Applications remain available as data, indexes, and models evolve, eliminating disruptive rebuilds, scheduled refreshes, and maintenance windows.

This enables organizations to combine proprietary content with customer-specific information while ensuring AI applications always retrieve the latest available knowledge.

For example, Perplexity combines its indexed knowledge base with files uploaded by Pro users, allowing retrieval across both public and private information within a single workflow.

4. Internet-Scale Performance

AI dramatically changes the economics of retrieval

Traditional search applications typically perform a single retrieval for each user query. AI agents and deep research workflows may perform dozens, or even hundreds, of retrieval operations before producing a response.

Retrieval infrastructure designed for human-speed search can quickly become overwhelmed by these new workloads. As retrieval volumes increase, latency becomes harder to predict, infrastructure costs rise, and systems built from multiple specialized components become increasingly difficult to scale efficiently.

Vespa was built for internet-scale serving from the beginning. It partitions and distributes data automatically across clusters while executing retrieval, ranking, filtering, and machine-learning inference where the data resides. Nodes can be added, removed, or upgraded without interrupting queries or writes, allowing applications to scale elastically as both data volumes and AI workloads grow.

The result is predictable performance, lower infrastructure costs, and the ability to support billions of documents, thousands of concurrent queries, and continuously evolving AI applications.

The answer


Retrieval Engineering in Practice

Retrieval Engineering in Practice

The principles described in this guide already power some of the world's most demanding AI applications, delivering retrieval, ranking, and real-time AI serving at internet scale.

  • AI-powered market intelligence over 500 million premium business documents.

    AlphaSense combines proprietary business content with AI-powered search built on Vespa's AI Search Platform to help professionals investigate, reason, and make faster decisions across finance, life sciences, and corporate strategy.

  • Delivering AI answers at internet scale

    Perplexity relies on Vespa to power retrieval across the public web, supporting fast, accurate answers with the performance required by millions of users.

  • Powering AI-driven search and recommendations at internet scale.

    Yahoo uses Vespa to power search, content recommendations, and advertising across its consumer properties. More than 150 Vespa applications serve over one billion users and process approximately 800,000 queries per second, demonstrating internet-scale retrieval, ranking, and AI serving.

Summary

Artificial intelligence is changing how travelers discover, compare, and book travel experiences. Rather than simply searching for flights, hotels, or destinations, they increasingly expect intelligent applications that understand intent, recommend alternatives, answer questions, and help them make better travel decisions. Delivering these experiences requires more than connecting a large language model to travel data. It requires engineering retrieval workflows that balance search quality, personalization, freshness, latency, scalability, and infrastructure efficiency. Prompt engineering influences how a model reasons. Retrieval Engineering determines what it has to reason about. As AI applications evolve from conversational assistants to increasingly capable AI agents, fragmented AI architectures become more difficult to scale. Search engines, vector databases, rerankers, and inference services each solve part of the problem. The engineering challenge is bringing them together into a retrieval architecture that remains accurate, responsive, and operationally simple. Vespa addresses that challenge by unifying search, ranking, machine learning inference, and real-time serving within a single AI Search Platform. The result is a simpler architecture that delivers more relevant traveler experiences, predictable performance, and efficient infrastructure as AI workloads continue to grow. The next generation of travel applications will compete not only on the destinations they offer, but on how intelligently they help travelers discover, compare, and plan their journeys. Retrieval Engineering is becoming the discipline that makes those experiences possible.

About Vespa.ai

Vespa.ai develops the Vespa AI Search Platform that brings retrieval, ranking, machine-learning inference, and real-time serving together within a single distributed architecture. Rather than stitching together fragmented search and AI retrieval components, Vespa executes the complete retrieval workflow close to the data, delivering high relevance, predictable latency, and operational simplicity at scale. Organizations including Yahoo, Spotify, Perplexity, and AlphaSense use Vespa to power mission-critical customer-facing applications.

Interested to learn more? We have many different resources and information available through our social platforms